
-
BacDive
BacDive
BacDive (The Bacterial Diversity Database) is the world’s largest knowledge base of standardized, strain-level bacterial and archaeal information. Recognized as both an ELIXIR Core Data Resource and a Global Core Biodata Resource, BacDive mobilizes and makes freely available research data from culture collections, species descriptions, and other curated sources. The database currently contains more than three million data points on over 100,000 strains, covering taxonomy, morphology, physiology, metabolism, origin, biosafety, sequence data, and cultivation.
Key benefits
Comprehensive strain-level information for more than 100,000 bacterial and archaeal strains
More than 1,000 standardized data fields across a broad range of biological and experimental topics
Manually curated data from species descriptions and international culture collections
Powerful search tools for identifying strains by phenotype, growth conditions, habitat, or isolation source
Programmatic access through a RESTful API and SPARQL endpoint
Recognized as an ELIXIR Core Data Resource and a Global Core Biodata Resource
Applications
Identification of strains with specific physiological or metabolic characteristics
Search for organisms isolated from particular environments or host-associated habitats
Selection of strains for cultivation and experimental studies
Comparative analysis of microbial traits and phenotypes
Linking strain-level information with sequence and biosafety data
Large-scale data retrieval and knowledge-graph-based analyses via API or SPARQL
Intended useBacDive is intended for microbiologists, microbial ecologists, taxonomists, bioinformaticians, data scientists, and biotechnology researchers who require comprehensive and standardized information on bacterial and archaeal strains. It is particularly suited for users searching for strains with defined biological characteristics or integrating curated strain-level data into large-scale computational analyses.
Contact:
WebsiteThis email address is being protected from spambots. You need JavaScript enabled to view it. -
BakRep
BakRep
BakRep is a comprehensive, scalable web repository that aggregates and standardizes millions of publicly available bacterial genomes from e.g. AllTheBacteria. Each genome is enriched with uniform quality metrics, taxonomic classification, sequence typing, and annotation, enabling rapid and reproducible comparative analyses across large datasets, and integrated with accompanying submission metadata.
Key BenefitsExtensive data coverage with consistently processed bacterial genomes.
Integrated Metadata: original submission metadata comprising e.g. sampling location, data, source.
Standardized genome characterizations, including QC, taxonomy, MLST, and annotation.
Powerful search and filtering to compile custom genome sets based on genomic or metadata attributes.
Web interface and command-line access for both exploratory and automated high-throughput workflows.Features
Unified pipeline for QC, taxonomic assignment, sequence typing, and annotation.
Advanced search by species, genome size, GC content, contig count, sequence type, and more.
Downloadable genome subsets for downstream computational analyses.
CLI integration for large-scale or reproducible workflows.Applications
Comparative genomics, phylogenetics, and population genomics.
Large-scale surveys of resistance genes, virulence factors, or metabolic traits.
Building curated genome datasets for benchmarking or tool development.
Supporting epidemiological investigations and outbreak analyses.Intended Use
BakRep is ideal for microbial genomics researchers, bioinformaticians, and epidemiologists who need reliable, standardized access to large bacterial genome collections.
Contact:
Website https://github.com/ag-computational-bio/bakrep-web -
Berlin RNA Toolbox
Berlin RNA Toolbox
The Berlin RNA Toolbox is a comprehensive collection of bioinformatics tools and databases. The toolbox offers a wide range of resources for researchers to analyze, predict, and understand various aspects of RNA biology.
Key Benefits
Comprehensive analysis of RNA interactions : Identify potential binding sites of microRNAs on messenger RNAs (mRNAs) and explore the complex relationships between RNAs.
In-depth analysis of circular RNAs : Discover circRNAs in RNA-seq data and explore their potential functions.
Accurate prediction of protein-RNA interactions : Identify specific binding regions between proteins and RNAs.Tools
PicTar : A microRNA target predictor that identifies potential binding sites of microRNAs on messenger RNAs (mRNAs).
miRDeep : A probabilistic model that detects the presence of expressed animal microRNAs in deep sequencing data.
PIPmiR : A tool to identify novel plant miRNA genes from a combination of deep sequencing and genomic features.
NASTIseq : Expression analysis for the identification of cis-Natural Antisense Transcripts (cis-NAT) from strand-specific RNA-seq data.
PARalyzer : A peak finder for protein-RNA interaction sites in PAR-CLIP data, helping to identify specific binding regions between proteins and RNAs.
microMUMMIE : MicroRNA target-site prediction in PAR-CLIP data, allowing researchers to predict potential microRNA binding sites within PAR-CLIP peaks.
cERMIT : A motif finder for large sequence sets e.g. from chromatin or RNA immunoprecipitation experiments, enabling users to identify conserved motifs across different sequences.Databases
doRiNA : A database of RNA interactions in post-transcriptional regulation, providing insights into the complex relationships between RNAs.
circBase : A database for public circular RNA datasets, allowing users to discover circRNAs in RNA-seq data and explore their potential functions.Target Audience
The Berlin RNA Toolbox is designed for researchers in the fields of molecular biology, bioinformatics, and computational biology. The tools and databases provided are particularly useful for scientists interested in understanding various aspects of RNA biology, including microRNA regulation, circular RNAs, and protein-RNA interactions.
Contact:
WebsiteThis email address is being protected from spambots. You need JavaScript enabled to view it. -
Bioconda & BioContainers – Package Management for Life-Science Software

Bioconda & BioContainers – Package Management for Life-Science Software
Bioconda is a community-driven software distribution for bioinformatics and life-science tools based on the Conda package manager. It provides easy access to thousands of curated software packages and supports reproducible installation and management of complex bioinformatics workflows. Bioconda packages are tightly integrated with BioContainers, enabling container-based execution of the same software.
Key Benefits:
Simple installation with automatic dependency resolution.
Reproducible environments through versioned packages and containers.
Broad coverage across genomics, transcriptomics, metagenomics, proteomics, and systems biology.
Flexible execution via Conda environments or containers.
Suitable for local systems, HPC, and cloud infrastructures.Features:
Large, community-maintained repository of bioinformatics software packages.
Automated building and testing to improve consistency and reliability.
Generation of BioContainers from Bioconda packages for container-based workflows.
Support for isolated Conda environments and container runtimes.
Compatibility with Linux and macOS systems.Applications:
Installation and management of bioinformatics software stacks.
Building reproducible analysis environments for research and training.
Running workflows in container-based systems and workflow managers.
Standard software provisioning in research infrastructures and core facilities.Intended Use:
For bioinformaticians, life-science researchers, and infrastructure providers who need reliable, reproducible software installation. Supports both Conda-based environments and containerized execution using BioContainers.Contact:
WebsiteThis email address is being protected from spambots. You need JavaScript enabled to view it. -
BioContextAI
BioContextAI
BioContextAI is a community hub that connects agentic artificial intelligence with biomedical resources and software via Model Context Protocol (MCP) servers. Its main goal is to foster the development of MCP servers for biomedical research applications that comply with the FAIR4RS principles (Findable, Accessible, Interoperable, and Reusable for Research Software). BioContextAI provides the BioContextAI Registry, a community-driven catalogue of MCP servers supporting AI-based biomedical research workflows. The Registry enables researchers and developers to discover, access, and contribute specialized MCP-based tools and databases enriched with structured metadata.
Key benefitsCommunity-driven registry of MCP servers for biomedical AI applications
Supports FAIR4RS-compliant software development
Enables integration of AI agents with biomedical databases and tools
Rich metadata to improve discoverability and interoperability
Encourages collaboration between AI developers and biomedical researchersApplications
Discovery and reuse of MCP servers for AI-supported biomedical workflows
Integration of large language models (LLMs) with biomedical tools and databases
Development of interoperable AI-driven research applications
FAIR4RS-oriented software development and community contribution
Exploration of agent-based AI approaches in life science researchIntended use
BioContextAI is intended for biomedical researchers, AI developers, research software engineers, and data infrastructure providers who aim to integrate agent-based AI systems with biomedical resources in a FAIR-compliant manner. Optional knowledge about LLM tool usage via MCP is beneficial for advanced development and integration scenarios.
Website
ContactIf you used this service, please help us improve by completing our short user survey.
Contact:
WebsiteThis email address is being protected from spambots. You need JavaScript enabled to view it. -
BRENDA
BRENDA
BRENDA – Comprehensive Enzyme Information System
BRENDA is one of the world's most comprehensive databases of enzyme functional information. It provides manually curated data on enzymes classified according to the Enzyme Commission (EC) nomenclature, covering thousands of EC numbers across all domains of life. The database contains experimentally validated information extracted from primary literature, including enzyme functions, kinetics, substrate specificity, regulation, and optimal reaction conditions. All entries are critically reviewed by experts to ensure high data quality and consistency.
Key benefits
Comprehensive, manually curated enzyme information database
Covers enzymes from more than 8,800 EC numbers
Includes experimentally validated functional and kinetic data
Information on substrates, products, inhibitors, cofactors, and enzyme regulation
Provides pH and temperature optima as well as expression data
Links to metabolic pathways and related biological databases
Freely accessible through a user-friendly web interface
Applications
Enzyme function annotation and characterization
Identification of enzyme substrates, products, and inhibitors
Investigation of enzyme kinetics and catalytic properties
Metabolic pathway analysis and reconstruction
Comparative enzymology and systems biology
Support for biotechnology, metabolic engineering, and drug discovery
Intended useBRENDA is intended for biochemists, molecular biologists, bioinformaticians, systems biologists, and biotechnology researchers seeking comprehensive, high-quality enzyme information. It is particularly suited for users requiring curated experimental data on enzyme function, kinetics, regulation, and metabolism for research, annotation, and computational modelling.
Contact:
WebsiteThis email address is being protected from spambots. You need JavaScript enabled to view it. -
CATS - Crop Analysis Tools Suite
CATS - Crop Analysis Tools Suite
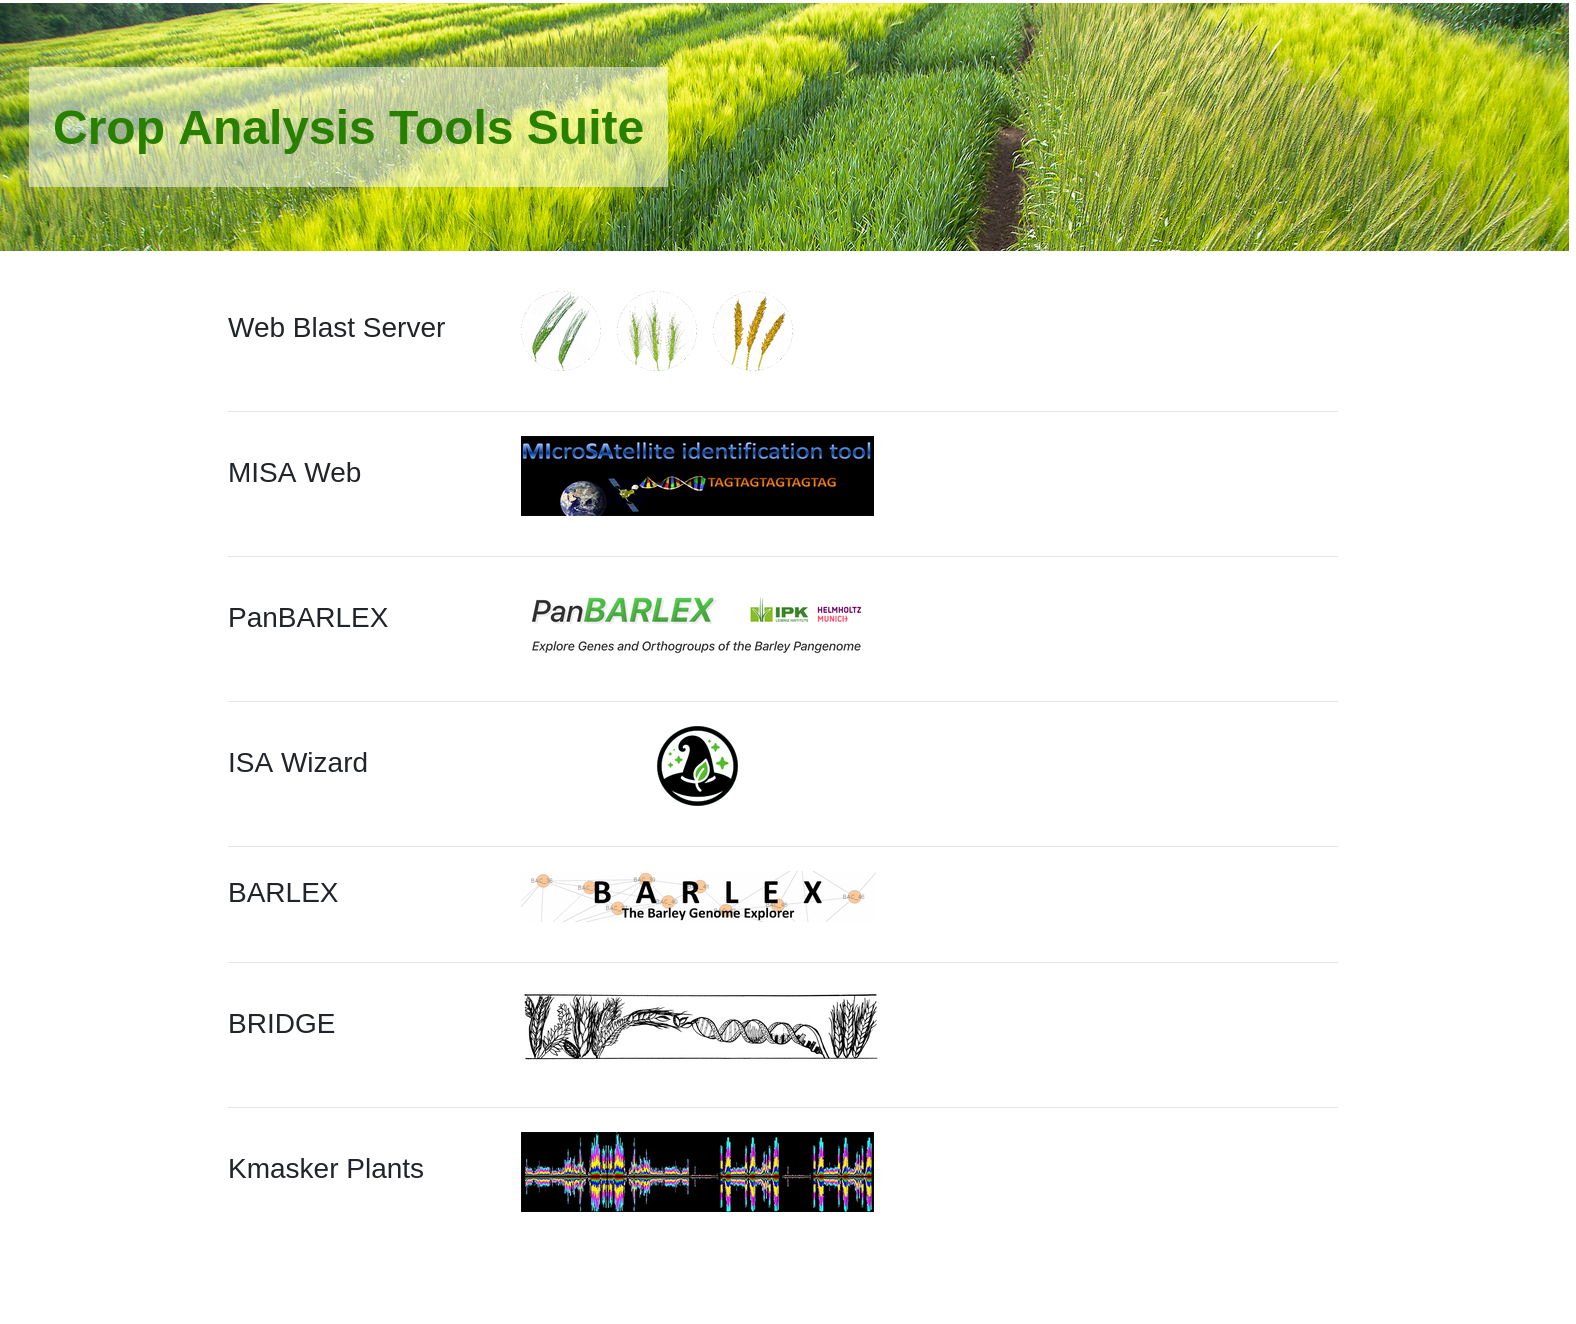
CATS (Crop Analysis Tools Suite) is an online platform that brings together a diverse collection of tools and resources for plant genome analysis, crop research, and research data management. The suite supports sequence similarity searches, microsatellite identification, genome and pan-genome exploration, crop diversity analysis, and the creation of FAIR and ISA-compliant metadata.
Key benefits
Central access to complementary tools for crop genome analysis and data management
Supports sequence search, genome annotation, visualization, and comparative genomics
Provides access to current crop reference and pan-genome resources
Includes tools for molecular marker and primer development
Facilitates barley genomics, genebank exploration, and crop diversity research
Supports FAIR and standardized metadata annotation for life science experimentsApplications
Homology searches against crop genome and pan-genome resources
Identification of microsatellites and development of molecular markers
Exploration of barley genes, orthologous groups, and genome annotations
Analysis of crop diversity, phenotypic traits, and sequence polymorphisms
Creation of standardized experimental metadata following ISA and MIAPPE principlesIncluded tools
Web BLAST Server – Web-based sequence similarity searches against current crop genome and pan-genome resources
MISA Web – Identification of microsatellites and generation of molecular markers or primers
PanBARLEX – Exploration of genes and orthologous groups across the barley pan-genome
ISA Wizard – User-friendly creation of FAIR and ISA-compliant metadata for life science experiments, including support for MIAPPE-based plant phenotyping metadata
BRIDGE – Exploration of the IPK barley genebank collection based on genetic diversity, phenotypic traits, and sequence polymorphismsIntended use
CATS is intended for plant geneticists, crop scientists, breeders, molecular biologists, bioinformaticians, and research data managers working with crop genome data and experimental metadata. It is particularly suited for researchers who need integrated access to tools for sequence analysis, genome exploration, marker development, crop diversity analysis, and FAIR data documentation.Contact:
WebsiteThis email address is being protected from spambots. You need JavaScript enabled to view it. -
Development of an integrated, deep learning-based system to support the curation of biomedical databases
Müller Group, Heidelberg Institute for Theoretical Studies, Service Center: de.NBI Systems Biology Service Center - de.NBI-SysBio
The BMBF-funded DeepCurate project (Computational Life Sciences (CompLS) -Deep Learning in Biomedicine) will support the previously manual curation process of scientific publications in biomedical databases using the SABIO-RK database as an example. SABIO-RK is a database for biochemical reactions and their kinetic properties. The curation in SABIO-RK mainly comprises the manual extraction as well as the standardization and annotation of data from the scientific literature to provide them in a structured, easily accessible and machine-readable form. Scientific publications are often unstructured. Existing automatic natural language processing (NLP) methods do not have the required coverage, robustness, and effectiveness to be used for the curation of high-quality databases. However, current advances in deep learning-based NLP allow the support of the curation process by using methods of automatic information extraction and thus make the process more effective and efficient. However, deep learning needs training data. DeepCurate explores innovative ways to use training data of various modalities (texts, images, eye trackings). In combination with current deep learning approaches, which can particularly benefit from multi-modal input, DeepCurate will be a very powerful tool that can also be adapted to other manually curated biomedical databases because it is not dependent on specific database models, ontologies, and scientific domains.
A first publication uses data from the SABIO-RK curation process to generate useful training data for deep learning approaches. Without the curation knowledge generated and maintained in de.NBI for more than a decade, the generation of such training data would be very expensive and time-consuming. The project exemplifies the interaction between service and research activities.
For further information, please visit SABIO-RK.
Funded by: BMBF, FKZ 031I0204
Search projects by keywords:
-
e!DAL-PGP - Plant Genomics and Phenomics Research Data Repository
e!DAL-PGP - Plant Genomics and Phenomics Research Data Repository
e!DAL-PGP is a research data repository for publishing and preserving plant genomics, phenomics, and other cross-domain research data. It is particularly suited for large or heterogeneous datasets that cannot be deposited in conventional domain-specific repositories because of their volume or data type. The repository supports structured metadata, persistent publication, data discovery, and programmatic access in line with the FAIR Principles.
Key benefits
Publication and long-term preservation of diverse plant research datasets
Supports large, complex, and cross-domain data collections
Structured metadata to improve findability, interoperability, and reuse
Searchable and browsable repository with dataset access and download statistics
Institutional authentication and data submission via ELIXIR AAI
Suitable for data accompanying scientific publications and collaborative projects
Applications
Publication of plant phenotyping and microscopy image collections
Deposition of unfinished genome assemblies and genotyping data
Sharing of mass spectrometry and other experimental datasets
Publication of plant-model visualizations, software, and research documents
Preservation of datasets that are too large or unsuitable for central domain repositories
Provision of FAIR research data for reuse in plant science and bioinformatics
Intended usee!DAL-PGP is intended for plant scientists, bioinformaticians, data stewards, and research projects that need a reliable repository for publishing, sharing, and preserving heterogeneous research data. It is particularly suited for large-scale or cross-domain datasets that require persistent access, rich metadata, and integration into FAIR research data workflows.
Contact:
WebsiteThis email address is being protected from spambots. You need JavaScript enabled to view it. -
EDGAR
EDGAR
EDGAR (Efficient Database Framework for Comparative Genome Analyses) is an online platform for comparative analysis of prokaryotic genomes. It supports the identification of orthologous genes and enables users to analyse core genomes, pan-genomes, and singletons across multiple bacterial genomes. EDGAR provides tools for exploring conserved and variable gene content, genome organization, synteny, and functional categories in comparative genomics studies.
Key benefits
Supports comparative analysis of bacterial and prokaryotic genomes
Identifies orthologous genes across multiple genomes
Calculates core genomes, pan-genomes, and singleton genes
Provides visualizations such as synteny plots and Venn diagrams
Enables functional categorization using resources such as KEGG, COG, and GO
Applications
Comparative genomics of related bacterial species or strains
Analysis of conserved and variable gene content
Core- and pan-genome analysis
Bacterial Taxonomy and Phylogenomics
Investigation of gene conservation, genome organization, and synteny
Functional interpretation of core and accessory genome components
Intended useEDGAR is intended for microbiologists, microbial genomicists, bioinformaticians, geneticists, and comparative genomics researchers working with bacterial or other prokaryotic genome data. It is particularly suited for users who want to compare multiple genomes, identify orthologous genes, analyse core and pan-genomes, and explore gene conservation, evolution, and function.
Contact:
WebsiteThis email address is being protected from spambots. You need JavaScript enabled to view it. -
eggNOG
eggNOG
eggNOG – Orthology and Functional Annotation Resource
eggNOG (evolutionary genealogy of genes: Non-supervised Orthologous Groups) is a database of hierarchically organized orthologous gene groups and their functional and evolutionary annotations. It provides orthology predictions across thousands of bacterial, archaeal, eukaryotic, and viral genomes, together with multiple sequence alignments, phylogenetic trees, and annotations from established functional resources. eggNOG supports comparative genomics and the transfer of functional information between evolutionarily related genes.
Key benefits
Hierarchically organized orthologous groups across numerous taxonomic levels
Broad coverage of bacterial, archaeal, eukaryotic, and viral genomes
Functional annotations linked to resources such as Gene Ontology, KEGG, UniProtKB, Pfam, CAZy, and CARD
Multiple sequence alignments and phylogenetic trees for orthologous groups
Interactive access through a web interface and bulk data downloads
Supports precise functional annotation based on orthology rather than general sequence similarity
Applications
Identification of orthologous genes and gene families
Functional annotation of genes and proteins
Comparative analysis of genomes, transcriptomes, and metagenomic gene catalogues
Investigation of gene-family evolution across taxa
Exploration of multiple sequence alignments and phylogenetic relationships
Transfer of functional annotations to newly sequenced organisms
Intended useeggNOG is intended for comparative genomicists, evolutionary biologists, microbiologists, bioinformaticians, and researchers analysing genomes, transcriptomes, or metagenomes. It is particularly suited for users who need orthology-based functional predictions and evolutionary context for genes or proteins.
Contact:
WebsiteThis email address is being protected from spambots. You need JavaScript enabled to view it. -
EURISCO - European Search Catalogue for Plant Genetic Resources
EURISCO - European Search Catalogue for Plant Genetic Resources
EURISCO (European Search Catalogue for Plant Genetic Resources) is a central gateway for information on plant genetic resources held in European collections. It provides access to more than two million germplasm accessions of cultivated plants and their wild relatives, which are conserved under ex situ or in situ conditions in over 450 collections across Europe and some neighbouring countries. EURISCO combines passport data with phenotypic information, enabling users to explore the diversity, origin and characteristics of plant genetic resources. EURISCO is operated on behalf of the European Cooperative Programme for Plant Genetic Resources (ECPGR).
Key benefits
Central access to information from hundreds of European PGR collections
More than two million germplasm accessions covering crops and crop wild relatives
Broad taxonomic coverage across thousands of genera and species
Integration of passport and phenotypic data
Supports discovery and comparison of plant genetic resources across institutions
Contributes to the conservation and sustainable use of agrobiodiversity
Applications
Identification of germplasm accessions with specific geographic, taxonomic or phenotypic characteristics
Support for crop breeding and pre-breeding research
Exploration of crop wild relatives and underutilised plant diversity
Comparative analysis of plant genetic resources across collections
Selection of material for phenotyping, genotyping and conservation studies
Research on agrobiodiversity, adaptation and genetic resource management
Intended useEURISCO is intended for plant breeders, genebank curators, crop scientists, geneticists, conservation researchers and bioinformaticians working with plant genetic resources. It is particularly suited for users who need a comprehensive overview of germplasm conserved in European collections and want to identify accessions for breeding, research, conservation or comparative analysis.
Contact:
WebsiteThis email address is being protected from spambots. You need JavaScript enabled to view it. -
GenomeCRISPR
GenomeCRISPR
GenomeCRISPR is a database for high-throughput screening experiments performed with the CRISPR/Cas9 system. It provides a dynamic web interface that helps users explore published CRISPR screens and retrieve information on observed hits, phenotypes, and experimental conditions. The database also contains information on the performance of individual single guide RNAs (sgRNAs), supporting the interpretation and comparison of CRISPR screening results.
Key benefits
Collects data from published high-throughput CRISPR/Cas9 screens
Provides information on observed hits and associated phenotypes
Includes sgRNA-level performance information across experimental conditions
Offers a dynamic web interface for searching and exploring screen data
Supports interpretation and reuse of CRISPR screening results
Applications
Exploration of published CRISPR/Cas9 screening experiments
Identification of genes associated with screened phenotypes
Assessment of sgRNA performance across different conditions
Comparison of hits from high-throughput genome editing screens
Support for planning and interpretation of CRISPR screening studies
Intended useGenomeCRISPR is intended for molecular biologists, genome engineers, functional genomics researchers, bioinformaticians, and CRISPR screening researchers. It is particularly suited for users who want to explore published CRISPR/Cas9 screens, investigate phenotype-associated hits, or evaluate sgRNA performance for experimental design and data interpretation.
Contact:
WebsiteThis email address is being protected from spambots. You need JavaScript enabled to view it. -
JSpeciesWS – Genome-Based Microbial Species Delineation
JSpeciesWS – Genome-Based Microbial Species Delineation
JSpeciesWS is a cloud-based bioinformatics service for pairwise comparison of microbial genomes at the whole-DNA level. It supports microbial systematics by calculating genome identity measures that are widely used for species circumscription and taxonomic assessment. The service provides established computational approaches that serve as faster in silico alternatives to traditional DNA-DNA hybridization methods formerly used for bacterial species delineation.
Key benefits
* Cloud-based genome comparison service without registration
* Supports microbial species delineation and taxonomic assessment
* Enables pairwise comparison of uploaded genomes and public references
* Provides access to an internal database of more than 70,000 quality-controlled bacterial genomes
* Allows previous analyses to be re-accessed and continued using anonymous session codesApplications
* Comparison of microbial genomes at whole-genome level
* Bacterial species delineation and taxonomic placement
* Identification of closely related reference organisms
* Analysis of newly sequenced or taxonomically ambiguous genomes
* Generation of pairwise genome comparison matrices for multiple organismsIntended use
JSpeciesWS is intended for microbiologists, microbial taxonomists, genome researchers, bioinformaticians, and researchers working with bacterial genome data. It is particularly suited for users who need accessible genome identity calculations to support microbial species circumscription, taxonomic decisions, or placement of unknown genomes among sequenced bacterial reference species.Service provision
This service is offered by the de.NBI Industrial Forum member Ribocon GmbH and is fully free for users from academia and industry, without registration. Development and maintenance are not funded by de.NBI.Contact:
WebsiteThis email address is being protected from spambots. You need JavaScript enabled to view it. -
LipidCompass

LipidCompass
LipidCompass – Interactive Exploration and Comparison of Quantitative Lipidomes
LipidCompass is a web-based database and analysis platform for the interactive exploration, comparison, and visualization of quantitative lipidomics datasets. It helps researchers navigate the lipid structural space and investigate lipid abundance patterns across samples, tissues, organisms, and studies. As part of the LIFS (Lipidomics Informatics for Life Science) ecosystem, LipidCompass serves as a FAIR resource for storing, exploring, and comparing lipidomics data using standardized nomenclature and metadata.
Key benefits
Interactive exploration of quantitative lipidomics datasets
Comparison of lipidomes within and across studies
FAIR data resource with standardized lipid annotations and metadata
Integration with established lipid databases and controlled vocabularies
Interactive visualization of lipid abundances and structural relationships
Supports lipidomics data submitted in standardized formats such as mzTab-M
Part of the broader LIFS lipidomics software ecosystem
Applications
Exploration and comparison of quantitative lipidomes
Identification of similarities and differences between biological samples
Cross-study comparison of lipidomics datasets
Investigation of tissue-, organism-, and condition-specific lipid profiles
Integration of lipidomics data into systems biology workflows
Interactive visualization and interpretation of lipidomics experiments
Intended useLipidCompass is intended for lipidomics researchers, mass spectrometry users, bioinformaticians, and systems biologists who need a centralized platform for exploring and comparing quantitative lipidomics data. It is particularly suited for users seeking FAIR-compliant data management, interactive visualization, and large-scale comparison of lipidomes across experiments and studies.
Contact:
WebsiteThis email address is being protected from spambots. You need JavaScript enabled to view it. -
LPSN
LPSN
LPSN – List of Prokaryotic Names with Standing in Nomenclature
LPSN (List of Prokaryotic Names with Standing in Nomenclature) is the authoritative online resource for the nomenclature of prokaryotes. Hosted by the DSMZ, it provides comprehensive and regularly updated information on validly published bacterial and archaeal names, their taxonomic status, nomenclatural history, and associated type strains. LPSN also integrates information from the Prokaryotic Nomenclature Up-to-date (PNU) service and links to type-strain genome data. Since 2023, LPSN has been recognized as a Global Core Biodata Resource.
Key benefits
Authoritative resource for prokaryotic nomenclature
Regularly updated according to the latest taxonomic and nomenclatural changes
Comprehensive information on validly published bacterial and archaeal names
Links to type strains and associated genome information
Integration of data from the Prokaryotic Nomenclature Up-to-date (PNU) service
User-friendly web interface with powerful search capabilities
Recognized as a Global Core Biodata Resource
Applications
Verification of valid bacterial and archaeal names
Taxonomic classification and nomenclature research
Identification of type strains and nomenclatural references
Support for genome annotation and microbial database curation
Comparative microbiology and microbial biodiversity studies
Reference resource for publications and taxonomic assignments
Intended useLPSN is intended for microbiologists, taxonomists, microbial ecologists, bioinformaticians, and life science researchers who require authoritative information on prokaryotic nomenclature and taxonomy. It is particularly suited for users involved in microbial classification, genome annotation, biodiversity research, and the curation of microbial databases.
-
MaCPepDB - Mass Centric Peptide Database

MaCPepDB - Mass Centric Peptide Database
MacPepDB is a database that enables fast and comprehensive access to all theoretically generated tryptic peptides derived from the UniProtKB. It allows users to query peptide sequences across organisms and proteomes, facilitating proteomics research that relies on in silico digestion and peptide-centric analyses.
Key benefitsFast retrieval of tryptic peptides derived from UniProtKB proteins
Organism- and proteome-wide peptide search capabilities
Supports peptide-centric workflows in proteomics research
Facilitates theoretical digestion-based analyses
Web-accessible database for immediate queryingApplications
In silico tryptic digestion of UniProtKB protein entries
Peptide lookup across species and proteomes
Support for mass spectrometry-based proteomics workflows
Assessment of peptide uniqueness and proteome coverage
Database support for method development and benchmarkingIntended use
MacPepDB is intended for researchers in proteomics, bioinformatics, and computational biology who require rapid access to theoretical tryptic peptides for database searches, method development, or peptide-centric analyses. It is particularly suited for users working with mass spectrometry data and proteome-wide peptide investigations.
Contact:
WebsiteThis email address is being protected from spambots. You need JavaScript enabled to view it. -
MediaDive
MediaDive
MediaDive is a comprehensive resource for cultivation media and growth conditions of microorganisms. It provides more than 3,000 standardized and manually curated media recipes for bacteria, archaea, fungi, yeasts, algae, and protists. In addition to searching and comparing established recipes, users can adapt existing media or create and share custom formulations using the integrated Medium Builder.
Key benefits
Extensive collection of standardized cultivation media
Expert curation by DSMZ specialists
Search options based on taxonomy and isolation source
Tools for comparing, modifying, and sharing media recipes
Integration with related DSMZ microbial resources
Programmatic access through a RESTful API
Accessible and user-friendly web interface
Applications
Identification of suitable cultivation media for microorganisms
Comparison of media formulations and growth conditions
Design and adaptation of custom media recipes
Support for microbial isolation and cultivation experiments
Linking cultivation information with strain and taxonomy data
Integration of media data into laboratory and bioinformatics workflows
Intended useMediaDive is intended for microbiologists, culture collection staff, microbial ecologists, biotechnology researchers, and laboratory scientists who need reliable information on cultivation media and growth conditions. It is particularly suited for users planning microbial cultivation experiments, optimizing media formulations, or integrating standardized media information into experimental and computational workflows.
Contact:
WebsiteThis email address is being protected from spambots. You need JavaScript enabled to view it. -
Metalog
Metalog
Metalog is a repository of manually curated metadata for metagenomics samples from diverse habitats across the globe. It provides consistently annotated sample metadata for human, animal, marine, and other environmental microbiome studies. The resource contains 80,423 human samples, including 66,527 gut microbiome samples, 10,744 animal samples, 5,547 ocean water samples, and 23,455 samples from other environmental habitats such as soil, sediment, and fresh water.
Key benefits
Manually curated metadata repository for metagenomics samples
Covers human, animal, marine, and environmental microbiome datasets
Provides consistent annotation of habitat-specific core features
Supports global exploration and comparison of metagenomics samples
Helps improve metadata quality and reuse in microbiome research
Applications
Discovery of metagenomics samples by habitat or metadata features
Comparative microbiome studies across humans, animals, and environments
Selection of datasets for reanalysis or meta-analysis
Exploration of disease status, medication, host species, captivity, salinity, and other variables
Support for harmonized metadata use in large-scale microbiome research
Intended useMetalog is intended for microbiome researchers, metagenomics researchers, bioinformaticians, microbial ecologists, and data curators who need consistently annotated metadata for sample discovery, dataset comparison, and large-scale microbiome analyses. It is particularly suited for users who want to identify relevant metagenomics datasets across habitats and reuse metadata in a standardized way.
Contact:
WebsiteThis email address is being protected from spambots. You need JavaScript enabled to view it. -
metaTraits
metaTraits
metaTraits – Unified Microbial Trait Resource
metaTraits is a unified microbial trait resource that integrates experimentally derived trait information with genome-based trait predictions. It combines culture-derived data from resources such as BacDive, BV-BRC, JGI IMG, and GOLD with predictions for isolate genomes and metagenome-assembled genomes from proGenomes and SPIRE. Covering more than 2.2 million genomes and over 140 harmonized traits, metaTraits enables users to explore microbial morphology, physiology, metabolism, environmental preferences, and lifestyle features in a standardized framework.
Key benefits
Integrates culture-derived traits and genome-based trait predictions
Covers more than 2.2 million isolate and metagenome-assembled genomes
Provides over 140 harmonized microbial traits mapped to standardized ontologies
Links records to original evidence and source databases
Cross-referenced to both NCBI and GTDB taxonomies
Applications
Exploration of microbial traits across genomes and habitats
Comparative analysis of morphology, physiology, metabolism, and lifestyle features
Linking microbial genomes to environmental preferences such as temperature, salinity, and oxygen tolerance
Trait-based interpretation of microbiome and metagenomics datasets
Selection of organisms or genome groups based on functional or ecological traits
Intended usemetaTraits is intended for microbiome researchers, microbial ecologists, bioinformaticians, comparative genomics researchers, and data curators who need standardized access to microbial trait information. It is particularly suited for users who want to compare traits across microbial genomes, connect metagenomic findings with ecological or physiological properties, or integrate trait data into large-scale microbiome analyses.
Contact:
WebsiteThis email address is being protected from spambots. You need JavaScript enabled to view it.